Instagram Transcript Downloader: What the .txt File Actually Contains
A download button takes a minute to add and is almost never described. This page describes the file it produces: what is inside, what is missing, and how to tell a complete download from a cut one.
Main guide: Instagram transcript — paste a link, get the full text. The page you are reading covers one specific case in depth.
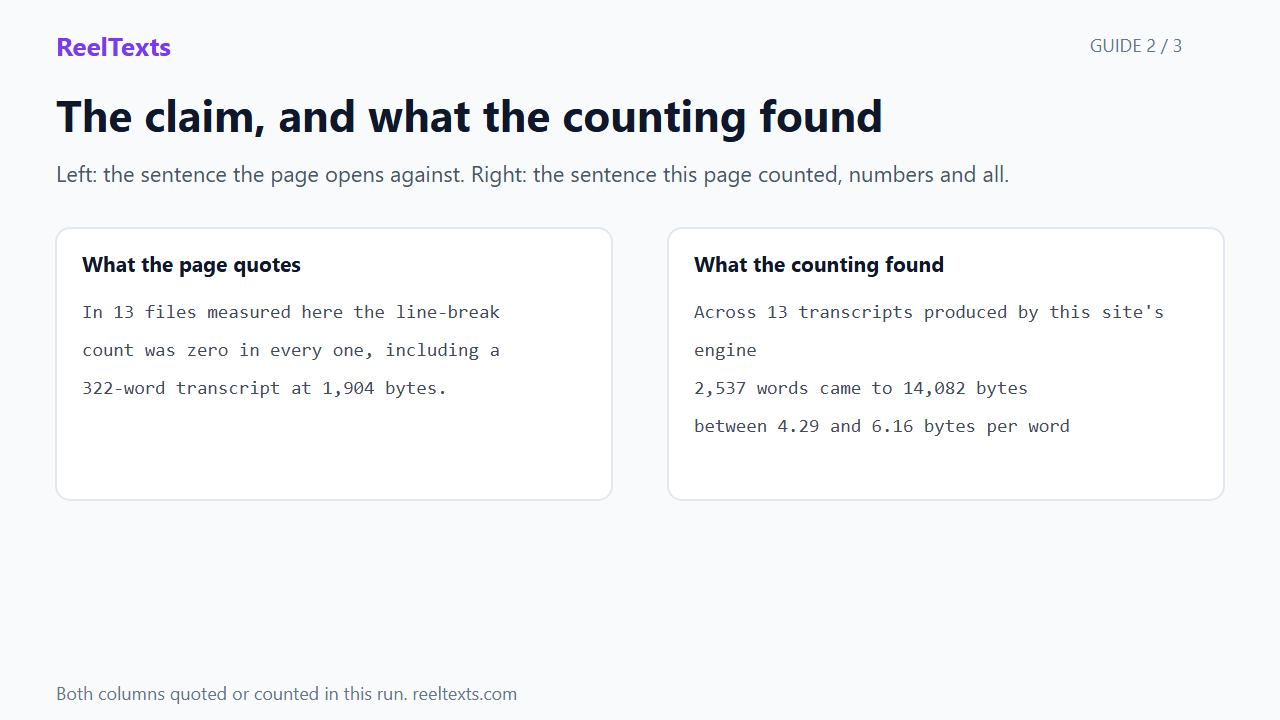
Short answer: the download is a single file named instagram-transcript.txt, and it holds the transcript as one unbroken line of plain text — no timestamps, no speaker names, no paragraph breaks, no video title, no source link. Across 13 transcripts produced by this site's engine, 2,537 words came to 14,082 bytes, between 4.29 and 6.16 bytes per word, and every one of the 13 files contained zero line breaks.
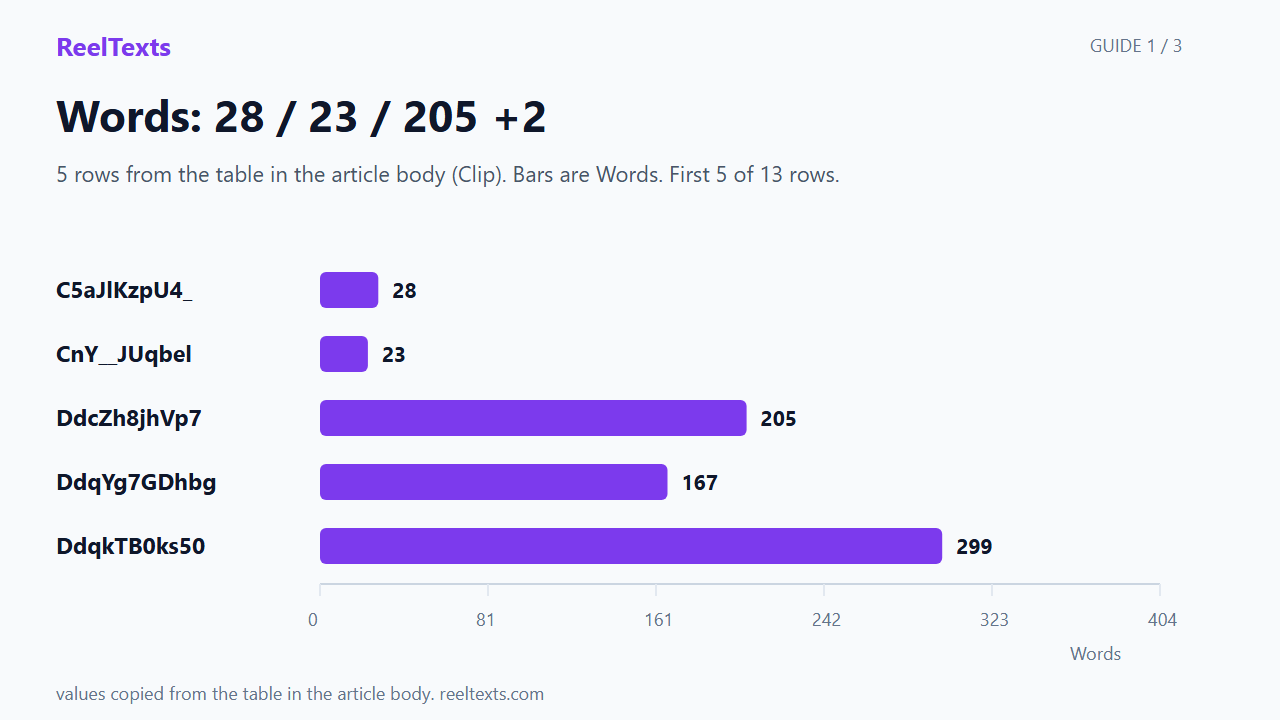
Visual guide: Words: 28 / 23 / 205 +2
Three slides: 5 rows from the table in the article body (Clip). Bars are Words. First 5 of 13 rows.
Watch the guide
Three slides, thirty seconds, English captions in the player. The video is silent by design; the captions carry the words.
The button writes one string, and the code says which one
The file is not assembled by a server. The transcript that appears on screen lives in one variable, and the download handler turns that same variable into a file: new Blob([currentText], { type: 'text/plain' }) at public/app.js line 181, with the name set to instagram-transcript.txt at line 184. Two consequences follow. Copy and download cannot disagree, because they read the same string. And the file carries no metadata of its own, because none is added.
The name is fixed, and the file records nothing about where it came from: no date, no source, no model. Keep more than one and you will need to rename at save time, because the second file looks exactly like the first.
What is not in the file
Four things people expect and do not get. There are no timecodes, so no line points back to a moment in the video. There are no speaker labels, so a quote cannot be attributed from the text alone. There are no paragraph breaks, so a four-minute clip arrives as one block. And there is no header: no video title, no account name, no date, no model name, no confidence mark. A file found on a desktop in six months identifies neither the video nor the day it was made.
Thirteen transcripts, measured
Every file below is engine output saved unedited, encoded the way the browser encodes the download (UTF-8, no byte-order mark). Bytes are the file size you would see on disk.
| Clip | Words | Bytes | Bytes per word | Line breaks |
|---|---|---|---|---|
| C5aJlKzpU4_ | 28 | 120 | 4.29 | 0 |
| CnY__JUqbel | 23 | 122 | 5.30 | 0 |
| DdcZh8jhVp7 | 205 | 1,224 | 5.97 | 0 |
| DdqYg7GDhbg | 167 | 1,028 | 6.16 | 0 |
| DdqkTB0ks50 | 299 | 1,615 | 5.40 | 0 |
| DdJV_VhE4Kj | 233 | 1,271 | 5.45 | 0 |
| Ddmsq-APsXb | 271 | 1,451 | 5.35 | 0 |
| DdhIGPFvD88 | 323 | 1,779 | 5.51 | 0 |
| Ddux1OTiIn7 | 106 | 574 | 5.42 | 0 |
| DdwV7-XCsZ4 | 130 | 686 | 5.28 | 0 |
| Ddv4nWFjTiB | 208 | 1,087 | 5.23 | 0 |
| Ddv7hsfNZnc | 222 | 1,221 | 5.50 | 0 |
| DdwIEyckv-Q | 322 | 1,904 | 5.91 | 0 |
Thirteen files, 2,537 words, 14,082 bytes, line-break count zero in all thirteen. Files saved 24 September and 18 October 2026; byte counts re-read on 26 October 2026. Words by whitespace, bytes as UTF-8.
One reel, two runs, eight days apart: 574 bytes both times
A 36.2-second reel was transcribed twice on this machine, on 18 October at 09:55 and again on 26 October at 03:51, both with the base English model at beam 5. Both runs returned 106 words and 574 bytes, and the two files are byte-identical down to the digest fb921934ed2198ed. The second run took 121.9 seconds of wall time and produced 951 bytes per minute of audio. If a download looks short, the cause is almost never the save step: the save writes exactly the string it was handed.
How to check your own download in under a minute
Four checks, each one cheap. Count the words in the file and compare with the count on screen before saving; a mismatch means the save was cut, not the transcript. Divide bytes by words and expect something between 4.3 and 6.2 — far below means a truncated tail, far above means repeated blocks. Look for the byte-order mark: this site's file has none, so a file that starts with three stray characters came from somewhere else. And open it in a spreadsheet if you want to see the structure plainly: with zero line breaks, the whole transcript lands in a single cell.
What this tool will not do
It takes Instagram links and nothing else. A youtube.com link sent to the endpoint returns HTTP 400 with the message “Please paste a public instagram.com post, Reel or IGTV link.” A dropbox.com share link and a drive.google.com share link get the same answer; a story URL gets it too. Files cannot be uploaded at all: the endpoint accepts JSON only, and a file posted to it returns HTTP 400 with “Body must be JSON.” The download is plain text and only plain text: one format on the page, one link at a time.
Questions
- Is the downloaded file the same as what I see on screen?
- Yes. Both come from one variable: the on-screen box prints it and the download handler wraps the same string in a text blob at
public/app.jsline 181. There is no second rendering step that could reformat the text. - Why does the whole transcript sit in one cell in Excel?
- Because the file contains no line breaks. In 13 files measured here the line-break count was zero in every one, including a 322-word transcript at 1,904 bytes. A single cell is the correct rendering of a single line.
- Can I get timestamps with the download?
- No. The file holds speech only: no timecodes, no speaker labels, no paragraph marks, no header. Anything that adds timing afterwards is spreading words across the clip by arithmetic, which is an estimate rather than a measurement.
Affiliate link: Notta is a separate service that transcribes audio and video files you upload. This site earns a commission if you subscribe through that link, at no extra cost to you.