Instagram Video to Text: Three Kinds of Text, One Comes Back
A Reel keeps words in three places: the audio track, the pixels on the frame, and the caption field. A video to text tool reads one. Three public Reels, 213.59 seconds: 352 words from the audio, 312 in the captions, 43 printed on the frames.
Main guide: Instagram transcript — paste a link, get the full text. The page you are reading covers one specific case in depth.
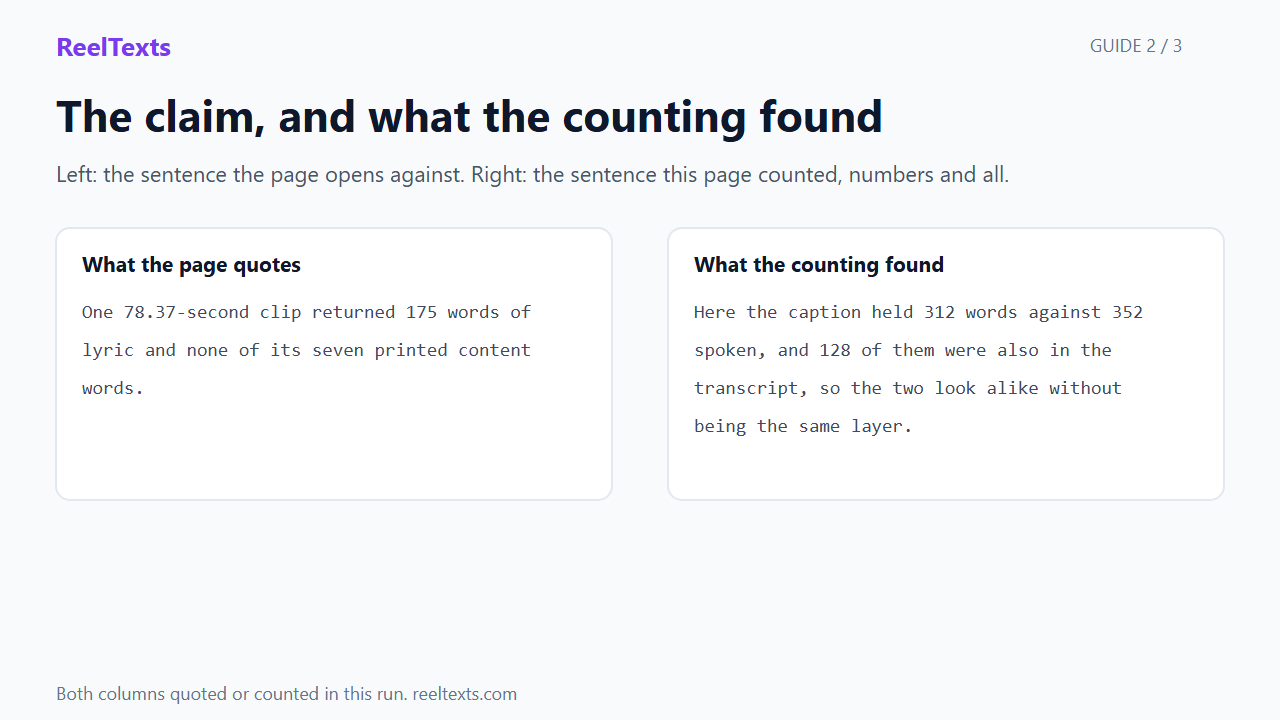
Short answer: you get the audio layer. It held 352 words; the captions held 312, 128 of them also spoken; the frames carried 43 distinct printed words, and the transcripts contain 7 of the 28 content words among them. When the audio is a music bed the layer that comes back is the wrong one: one clip returned 175 words of lyric and none of the seven content words printed on its frames.
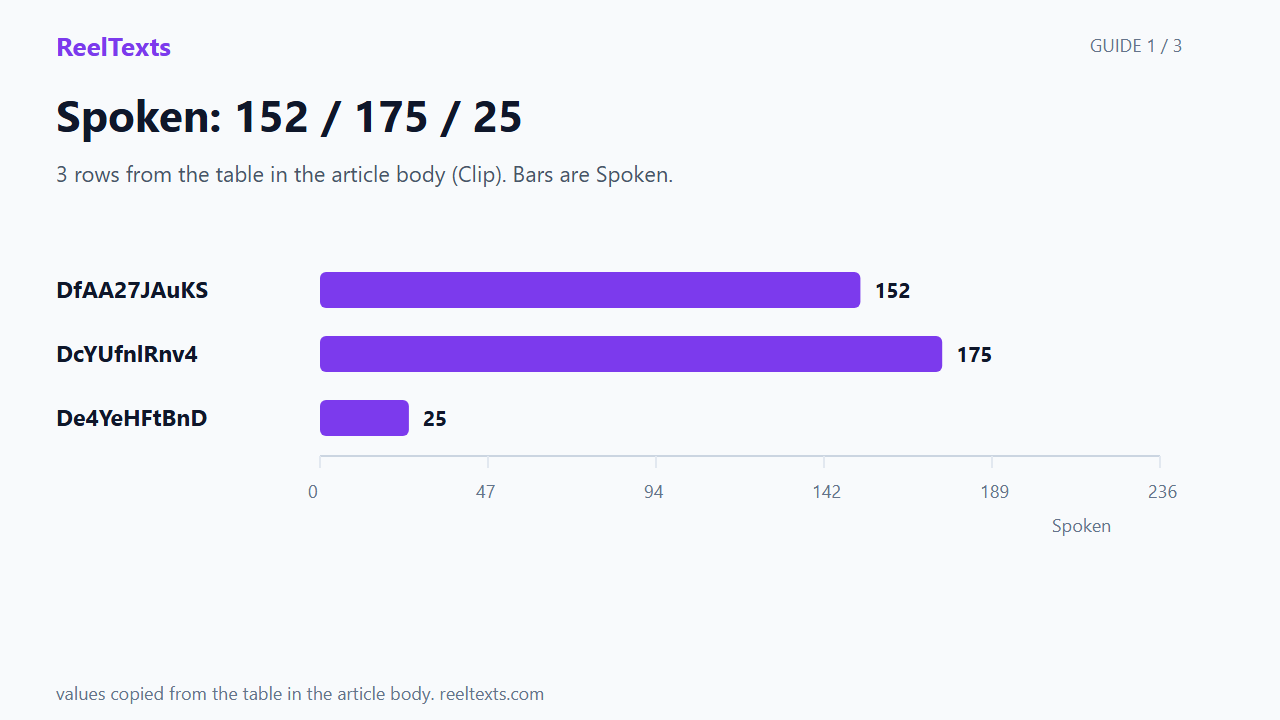
Visual guide: Spoken: 152 / 175 / 25
Three slides: 3 rows from the table in the article body (Clip). Bars are Spoken.
Watch the guide
Three slides, thirty seconds, English captions in the player. The video is silent by design; the captions carry the words.
Three places a Reel keeps words
A video is a picture with a soundtrack, and both carry writing. Only one of the three is spoken aloud.
| Layer | Where it lives | What the tool does | Words on 3 clips |
|---|---|---|---|
| Spoken | audio track | transcribed | 352 |
| Printed | pixels on the frame | not read at all | 43 distinct (28 content) |
| Caption | the post's description field | not included | 312 (128 also spoken) |
"Content words" excludes a, an, the, to, of, is, are, do, i, you, it, my, who, what, how, like and the same list.
213.59 seconds, three clips, 18 frames
Three public English Reels, 35.70 to 99.52 seconds. Each was transcribed by the engine this site runs, then six frames were cut at even intervals, tiled into one sheet and read.
| Clip | Length | Spoken | Caption | Caption in text | Frames with text | Distinct printed | Printed in text |
|---|---|---|---|---|---|---|---|
| DfAA27JAuKS | 99.52 s | 152 | 230 | 121 | 2 of 6 | 18 | 6 |
| DcYUfnlRnv4 | 78.37 s | 175 | 15 | 7 | 6 of 6 | 15 | 1 |
| De4YeHFtBnD | 35.70 s | 25 | 67 | 0 | 4 of 6 | 6 | 0 |
| Total | 213.59 s | 352 | 312 | 128 | 12 of 18 | 43 | 7 |
"Printed in text" counts distinct printed words appearing anywhere in that clip's transcript, function words included. On the second clip the single hit is "think".
The clip where the audio track was a song
DcYUfnlRnv4 is 78.37 seconds of someone making jalebi with music over it. The transcript came back as 175 words that read like lyrics: "Baby look in my car". Whatever the model heard, it was not a recipe.
All six sampled frames carried one line: "How do I explain Jalebi to people who think donuts are the peak of happiness". Seven content words. The transcript contains "think" and none of the other six: jalebi absent, donuts absent, happiness absent. The caption held 15 words, 7 of them in the transcript too.
The sentence that says what the video is about exists twice on the post and zero times in the file.
The clip that came back in another alphabet
De4YeHFtBnD is 35.70 seconds of chaat being assembled, and the speech is not English. The engine returned 25 words in a non-Latin script, which is automatic language detection doing its job: no language is specified on the way in, the decode settles on the language the audio actually is, and the text comes back in that script rather than in English or as an error. Four of six frames carried "Nobody does Chaat like a Bihari". The transcript contains none of its three content words, and none of the caption's 67.
The clip where the frame and the voice agreed
DfAA27JAuKS is the control: 99.52 seconds of a man explaining how an AI agent inspects an app, with two title cards cut in. He narrates what the cards show, so the layers overlap: 18 distinct printed words, 6 in the transcript, and all six are words he says while pointing at the diagram.
The cards also said "FRONT PAGE", "SERVER CODE", "VISIBLE FRONT PAGE", and closed on "Public view se private logic nahi milta." None of those twelve words is in the 152-word transcript.
What the four rival pages say
Four pages were read in full on 2026-10-29: getthescript.app on Instagram (411 words) and on video (433), saveto.ai on Instagram (1,476) and on video (1,148). speakapp.com served 29 words of placeholder copy: unverified, not empty.
Two say it outright. getthescript: "We pull the audio track and transcribe dialogue and narration with timestamps", and in its FAQ: "Only the audio track is used for transcription." saveto: "our AI tool can extract the audio and generate accurate transcripts, regardless of video length."
Across 3,468 words, "on screen", "printed", "overlay", "text layer", "ocr" and "burned" return zero hits. The nearest sentence is getthescript's "Our audio-first engine transcribes the spoken content, even under trending music and effects".
Getting the two layers the tool leaves behind
1. Read the caption before the transcript: it is the only layer that arrives as clean text, and here it held 312 words against 352 spoken.
2. When the transcript reads like a song, go to the frame. A printed line is often static, so one screenshot recovers it.
3. Treat the transcript as the audio layer. No re-run adds a title card, a price or an on-screen name.
This site does not read pixels: the engine takes an audio track and returns one string. It takes a public instagram.com post, Reel or IGTV link, no uploaded file, and refuses links from other platforms.
Questions
- Does Instagram video to text include the words printed on the screen?
- No. Of 18 sampled frames, 12 carried printed text and 43 distinct words; 7 of the 28 content words among them appear in the transcripts.
- Why did the transcript come back as song lyrics?
- Because the audio track is a music bed and the engine transcribes whatever is in it. One 78.37-second clip returned 175 words of lyric and none of its seven printed content words.
- Is the caption part of the transcript?
- No. Here the caption held 312 words against 352 spoken, and 128 of them were also in the transcript, so the two look alike without being the same layer.
Affiliate link: Notta is a separate service that transcribes audio and video files you upload. This site earns a commission if you subscribe through that link, at no extra cost to you.